Title: 3D Gaussian Splatting Rendering Performance Trade-offs on the Meta Quest 3

Authors: Milad Ghanbari, Hadi Amirpour, Christian Timmerer

Abstract

3D Gaussian Splatting (3DGS) is a compelling technique for real-time view synthesis, but its computational demands pose significant challenges for deployment on resource-constrained standalone eXtended Reality (XR) headsets. This paper presents a systematic performance study of 3DGS rendering on the Meta Quest 3, using a custom interactive tool that enables real-time control of render resolution scale, splat density, and frame rate cap through an in-world interface. We evaluate 180 conditions formed by the factorial combination of six resolution scales (0.5–1.0), ten splat density levels (10–100%), and three camera-to-object distances (0.7 m, 1.1 m, 1.5 m), with each condition repeated ten times. Performance metrics — GPU time, frame rate, GPU utilization, CPU utilization, power draw, and stale frame count — are captured via Meta’s Oculus Virtual Reality (OVR) Metrics Tool at a fixed target frame rate of 72 Hz. The results show that resolution scale is the dominant GPU cost driver due to the quadratic growth in pixel count, while splat density reduction is only an effective performance lever when GPU time is already close to the 72 Hz frame budget. Power draw is determined by total GPU work per time unit rather than cost per frame, which creates a counterintuitive relationship where lower resolution scales draw more power by enabling higher frame rates. These findings expose the interdependence between resolution scale, splat density, frame rate, and power, and establish a quantitative foundation for rendering parameter selection in 3DGS applications on standalone XR hardware.

Title: QoE and Depth Perception in Spatial Augmented Reality Darts

Authors: Milad Ghanbari, Yijue Huang, Wei Zhou, Patrick Le Callet, Christian Timmerer, Hadi Amirpour

Abstract

Accurate depth perception is critical for precision-based interaction in augmented reality applications, particularly in tasks that rely on ballistic motion such as throwing. While recent spatial computing devices support high-fidelity passthrough rendering and controller-free hand tracking, empirical evidence on how users perceive and act upon virtual depth in such environments remains limited. This paper investigates the effect of virtual target distance and time pressure on user performance and quality of experience in a physics-based augmented reality dart-throwing task implemented on the Apple Vision Pro. A controlled, repeated-measures user study with 22 participants evaluated performance at three target distances (near, standard, and far) and under a time-limited condition. Objective measures included score, hit accuracy, and throw timing, while subjective measures captured perceived depth, immersion, control, enjoyment, comfort, progress, time pressure, and adaptation. Results show a clear decrease in throwing accuracy as target distance increased, indicating limits in actionable depth perception despite visually stable spatial rendering. Under time pressure, participants significantly increased throwing speed without a corresponding loss in accuracy, suggesting robust motor execution once the interaction model was learned. Subjective ratings of control and depth understanding remained high across conditions, even when objective performance varied. These findings provide quantitative evidence that modern passthrough augmented reality systems can support reliable controller-free precision interaction, while also clarifying how depth and cognitive demand shape user performance and experience.

Title: EnerGP: Energy Evaluation in Video Game Style Post-Processing

Authors: Milad Ghanbari, Hadi Amirpour, Christian Timmere

Abstract

We present EnerGP, an interactive demo running on the Meta Quest 3 standalone eXtended Reality (XR) headset that enables real-time control over various video game-style post-processing effects in a Virtual Reality (VR) environment. The demo lets users observe the asymmetric relationship between post-processing effects and power consumption. While real-time rendering creates additional GPU overhead for each active post-processing pass, pre-rendered video or streamed video with the same effects baked in, results in measurably lower visual complexity, and thus a reduced hardware-accelerated decoding burden. We validate this finding through a pilot study that used the Enhanced Video Complexity Analyzer (EVCA) by comparing a pre-rendered 3D scene exported with and without seven post-processing effects: (1) Bloom, (2) Depth of Field, (3) Motion Blur, (4) Fog Volume, (5) Color Grading, (6) Screen-Space Ambient Occlusion (SSAO), (7) Temporal Anti-Aliasing (TAA). Results show that post-processing reduces spatial complexity by 17.1% and temporal complexity by 37.1% in the video condition. The demo, deployed on Meta Quest 3, allows users to toggle effects in real time and observe live power and performance metrics via the OVR Metrics Tool.

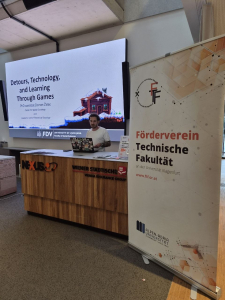
On September 2nd 2026, Dr Felix Schniz organised a Video Game Cultures Meet-and-Greet event. Supported by ITEC and the Förderverein technische Fakultät, this newly conceptualized event was supposed to create a bridge between students in technical master’s programmes, on PhD tracks working with technology, and even later career steps that are, in one capacity or another, involved with video games. Attendees, especially from bachelor’s programmes or those not studying yet, had the opportunity to meet, mingle, and ask questions about how to find their way into the technical sciences. With around forty people joining us at the Nexus coworking space, the event was well attended.

Title:  Cloud, Edge, or Split? Profiling Onboard and Split Vision-Language Model Deployment for Drone AI

Authors: Zoha Azimi, Reza Farahani, Schahram Dustdar, Christian Timmerer

The 4th International Symposium on Edge Intelligence, Trustworthy and Decentralized Artificial Intelligence (iEDGE 2026) 

October 27-30, 2026 – Paris, France

Abstract:

Vision-Language Models (VLMs) enable edge devices like unmanned aerial vehicles (UAVs) to interpret visual observations and reason about complex environments using natural-language instructions. However, their practical deployment remains challenging as onboard inference is constrained by limited computational, memory, and energy resources, whereas cloud-based inference introduces communication latency, bandwidth overhead, and dependence on network connectivity. To address these limitations, split computing offers a promising alternative by partitioning VLM inference between the resource-constrained UAVs and more capable remote servers. However, the performance trade-offs among fully onboard, cloud-based, and split-computing architectures for lightweight VLMs have not yet been systematically profiled. This paper benchmarks these three deployment paradigms using SmolVLM-256M as a representative lightweight VLM. We quantify their inference latency, computational resource utilization, communication overhead, and energy consumption across varying image resolutions and network conditions. Our results show that no deployment strategy is universally optimal; instead, the preferred strategy depends on the interaction between network conditions and input image resolution.


Konferenz: IEEE AGCS 2026 (Symposium on Edge intelligence, Trustworthy and Decentralized Artificial Intelligence- iEdge)

Wo: 27-30 October 2026, Paris, France.

Titel: A Multi-Node Performance Evaluation of Shared Edge AI Inference

Autoren: Raphael Walcher, Dragi Kimovski, Kurt Horvath

Abstract: 

Edge-based Artificial Intelligence (AI) enables latency-sensitive applications by moving inference closer to data sources. While previous studies have demonstrated the feasibility of inference offloading for individual edge devices, the scalability of shared inference resources under concurrent workloads remains insufficiently understood. This paper experimentally evaluates a multi-node Edge AI architecture in which three roadside units (RSUs) concurrently offload object detection sharing a Zone Processor (ZP) connected through Wi-Fi 6E.

A comprehensive experimental campaign comprising 648 parameter configurations investigates the impact of AI model complexity, capture frame rate, image encoding, and multi-node contention on throughput, latency, and system scalability.

The results demonstrate that inference offloading consistently outperforms local execution on resource-constrained RSUs, reducing end-to-end latency by up to two seconds for computationally demanding models. Throughput analysis further reveals model-dependent computational saturation limits of approximately 18 FPS, 9 FPS, and 3 FPS aggregate throughput for YOLOv5n, YOLOv5s, and YOLOv5m, respectively. Latency component analysis shows that inference execution and the resulting queue waiting account for more than 95% of the end-to-end latency, whereas transmission contributes only a small and nearly constant fraction. These findings establish model complexity and shared inference capacity, rather than communication latency, as the dominant factors governing the performance and scalability of shared Edge AI deployments.

Titel:

In-Service Wind Turbine Blade Inspection: A Multi-UAV Architecture Design and Preliminary Validation

Autoren:

Mario Leopold, Klaus Schöffmann, Farzad Tashtarian

Venue:

IEEE Access


Abstract:

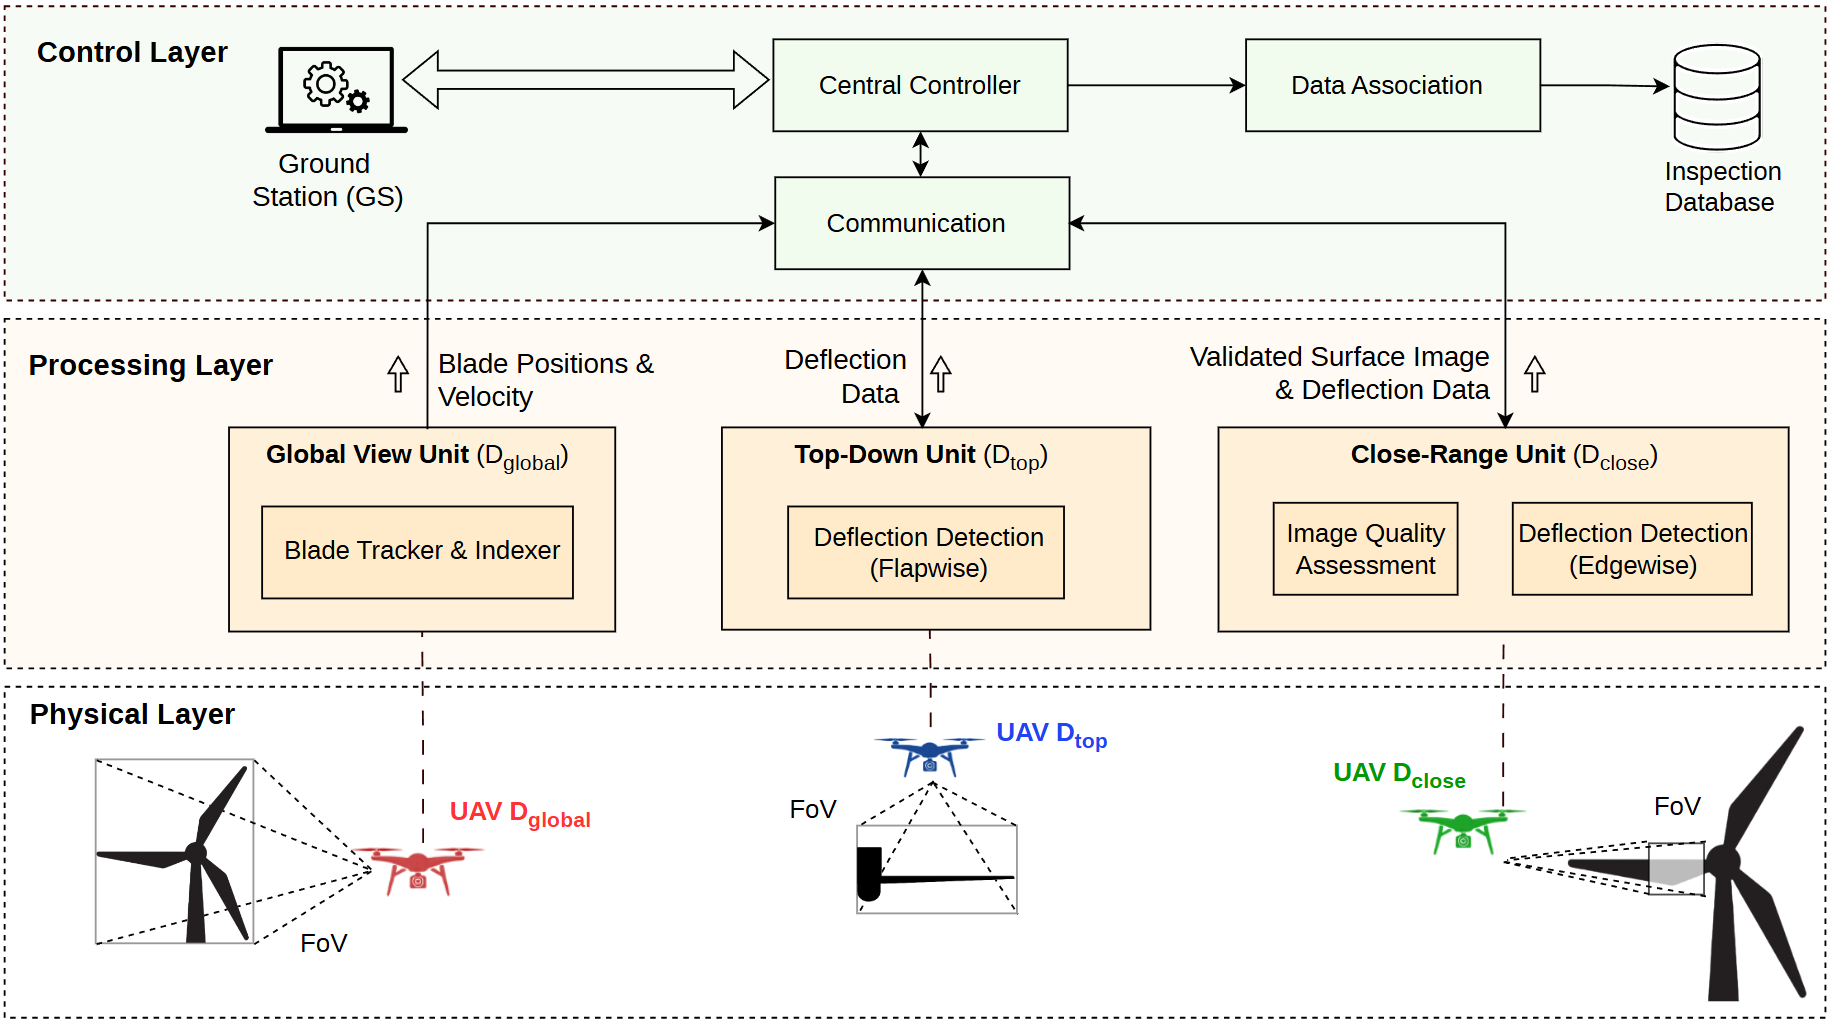
Wind turbine blade inspections are critical for ensuring structural integrity and minimizing operational downtime. However, existing methods, such as single Unmanned Aerial Vehicle (UAV) inspections, are limited by trade-offs among coverage, resolution, operational constraints, and often require turbine shutdown. This paper presents a multi-UAV inspection architecture design for in-service wind turbine blade inspection. The proposed architecture design provides a scalable framework for multi-UAV-based inspection of wind turbines during operation, enabling data acquisition without halting the turbine. The system distributes tasks across multiple UAVs, enabling simultaneous global observation, close-range surface imaging, and deflection detection. A ground station is introduced to coordinate the system, aggregate multi-view data, and offload computationally intensive processing. By separating global and local perception tasks, the architecture addresses key limitations of single-UAV systems and supports synchronized data acquisition during regular wind turbine operation. The core components of the system are implemented and evaluated using a scaled wind turbine model. Results demonstrate stable, persistent blade identification, reliable deflection estimation during rotation, and a component-level preliminary validation on embedded hardware platforms in terms of computational and energy requirements.

Interns at ATHENA (Summer 2026)

In July 2026, the ATHENA Christian Doppler Laboratory hosted four interns working on the following topics:

  • Leon Kordasch – Holography
  • Daniel Glantschnig – Automated Wind Turbine Damage Detection
  • Gabriel Puri – Adaptive Streaming for Immersive Media

At the end of their internships, the interns presented their projects and findings and received official university certificates in recognition of their work. The experience proved valuable for both the interns and the ATHENA research team alike. Through personalized mentorship, hands-on training, and continuous support, the interns were able to develop strong practical skills while gaining a deeper understanding of research methodologies and technologies in the video streaming domain. We warmly thank the interns for their enthusiasm, dedication, and thoughtful feedback, which made a meaningful contribution to the ongoing work of the ATHENA lab.

Leon Kordasch: “During my internship, I worked on digital holography. I explored state-of-the-art solutions, analyzed their performance and gained lots of theoretical knowledge and technical experience. While challenging, the internship was very rewarding. My supervisor, Ayman Alkhateeb, provided guidance where needed, and collaborating with a diverse, international team made the experience both enriching and enjoyable.”

Daniel Glantschnig: “My time as an intern was both interesting and rewarding. I had the opportunity to train object detection models using datasets with and without synthetic data, then compare the results to explore how synthetic data influenced model performance. Working on this project helped me gain a much better understanding of dataset preparation, model training, evaluation, and the impact that different types of data can have on object detection systems. One of the highlights of the internship was the welcoming and friendly team, which made the experience even more enjoyable. I also greatly appreciated the support of my supervisor from the DORBINE project, Mario, who was always available to answer my questions and help me work through any challenges. The internship allowed me to apply my existing knowledge in a practical environment while developing new technical skills. Overall, I am very grateful for the opportunity, the guidance I received, and the valuable experience I gained during my time there.”

Gabriel Puri: “Over the past four weeks as an intern, I’ve had a wonderful experience. I had the opportunity to work on streaming immersive media to the Apple Vision Pro, and I even created a Swift application that streams spatial videos to a local server. This server processes the incoming stream using my integrated pipeline, which enables adaptive bitrate streaming. I’ve learned a lot about encoding and how it’s done in real-world applications such as Netflix streams. I’ve also learned through trial and error, for example by trying an approach and failing, but eventually succeeding. I also learned how to accurately grade video quality via AVQT. One of the most memorable aspects of the internship was undoubtedly the incredibly welcoming and inclusive team, as well as my supervisor and mentor, Kamran from the ATHENA project. He is a true expert in his field and provided me with crucial support. This internship has allowed me to apply my interest in computer science to useful real-world scenarios and gain industry insights. Overall, I am incredibly grateful for this opportunity and for all the guidance and support I received throughout the internship.“

Title: DRLM: Deep Reinforcement Learning-Based LLM Query Orchestration in Edge Environments


Authors: Reza Farahani (TU Wien, Austria), Zoha Azimi (AAU, Austria), Mario Colosi (University of Messina, Italy), Lauri Lov\’en (University of Oulu, Finland), Christian Timmerer (AAU, Austria), Schahram Dustdar (TU Wien, Austria)


Venue: IEEE Global Communications Conference (GLOBECOM), Macau S.A.R., China, 7 – 11 December 2026


Abstract:

Large language model (LLM) services increasingly process heterogeneous queries with diverse latency, accuracy, and resource requirements. While edge deployment reduces response time, the heterogeneity of devices and the diversity of model families, parameter scales, and quantization levels make efficient LLM query orchestration challenging. This paper introduces DRLM, a Deep Reinforcement Learning-based LLM query orchestration framework in edge environments. DRLM integrates two lightweight predictors: (i) a class-conditioned quality estimator that maps queries to semantic categories and infers model performance, and (ii) a feature-driven latency predictor that estimates inference time across model-device configurations. These predictions, combined with system state (resource utilization and queue dynamics), feed a factorized Proximal Policy Optimization (PPO) agent that performs state-aware orchestration decisions. To enable data-driven orchestration, we construct a large-scale benchmarking dataset with 223 835 measurements spanning 1258 queries, 6 query classes, 8 model families (32 deployed instances), 5 quantization levels, and heterogeneous edge devices. Evaluation on a realistic 64-node edge cluster and comparison with three baselines and two state-of-the-art methods show that DRLM reduces inference latency by up to 51 % and queuing delay by up to 67 %, while incurring at most 8 % accuracy loss. DRLM further improves latency under increasing workloads up to 61.4 %, demonstrating robust and stable orchestration.


Depth-Aware Stereo Bitrate Ladder Optimization with Decoding-Time Constraints for HTTP Adaptive Streaming


IEEE International Workshop on Multimedia Signal Processing (MMSP)

September 22 – September 24, 2026

Istanbul, Turkey

[PDF]

Kamran Qureshi (AAU, Austria), Hadi Amirpour (AAU, Austria), Farzad Tashtarian (AAU, Austria), Christian Timmerer (AAU, Austria)

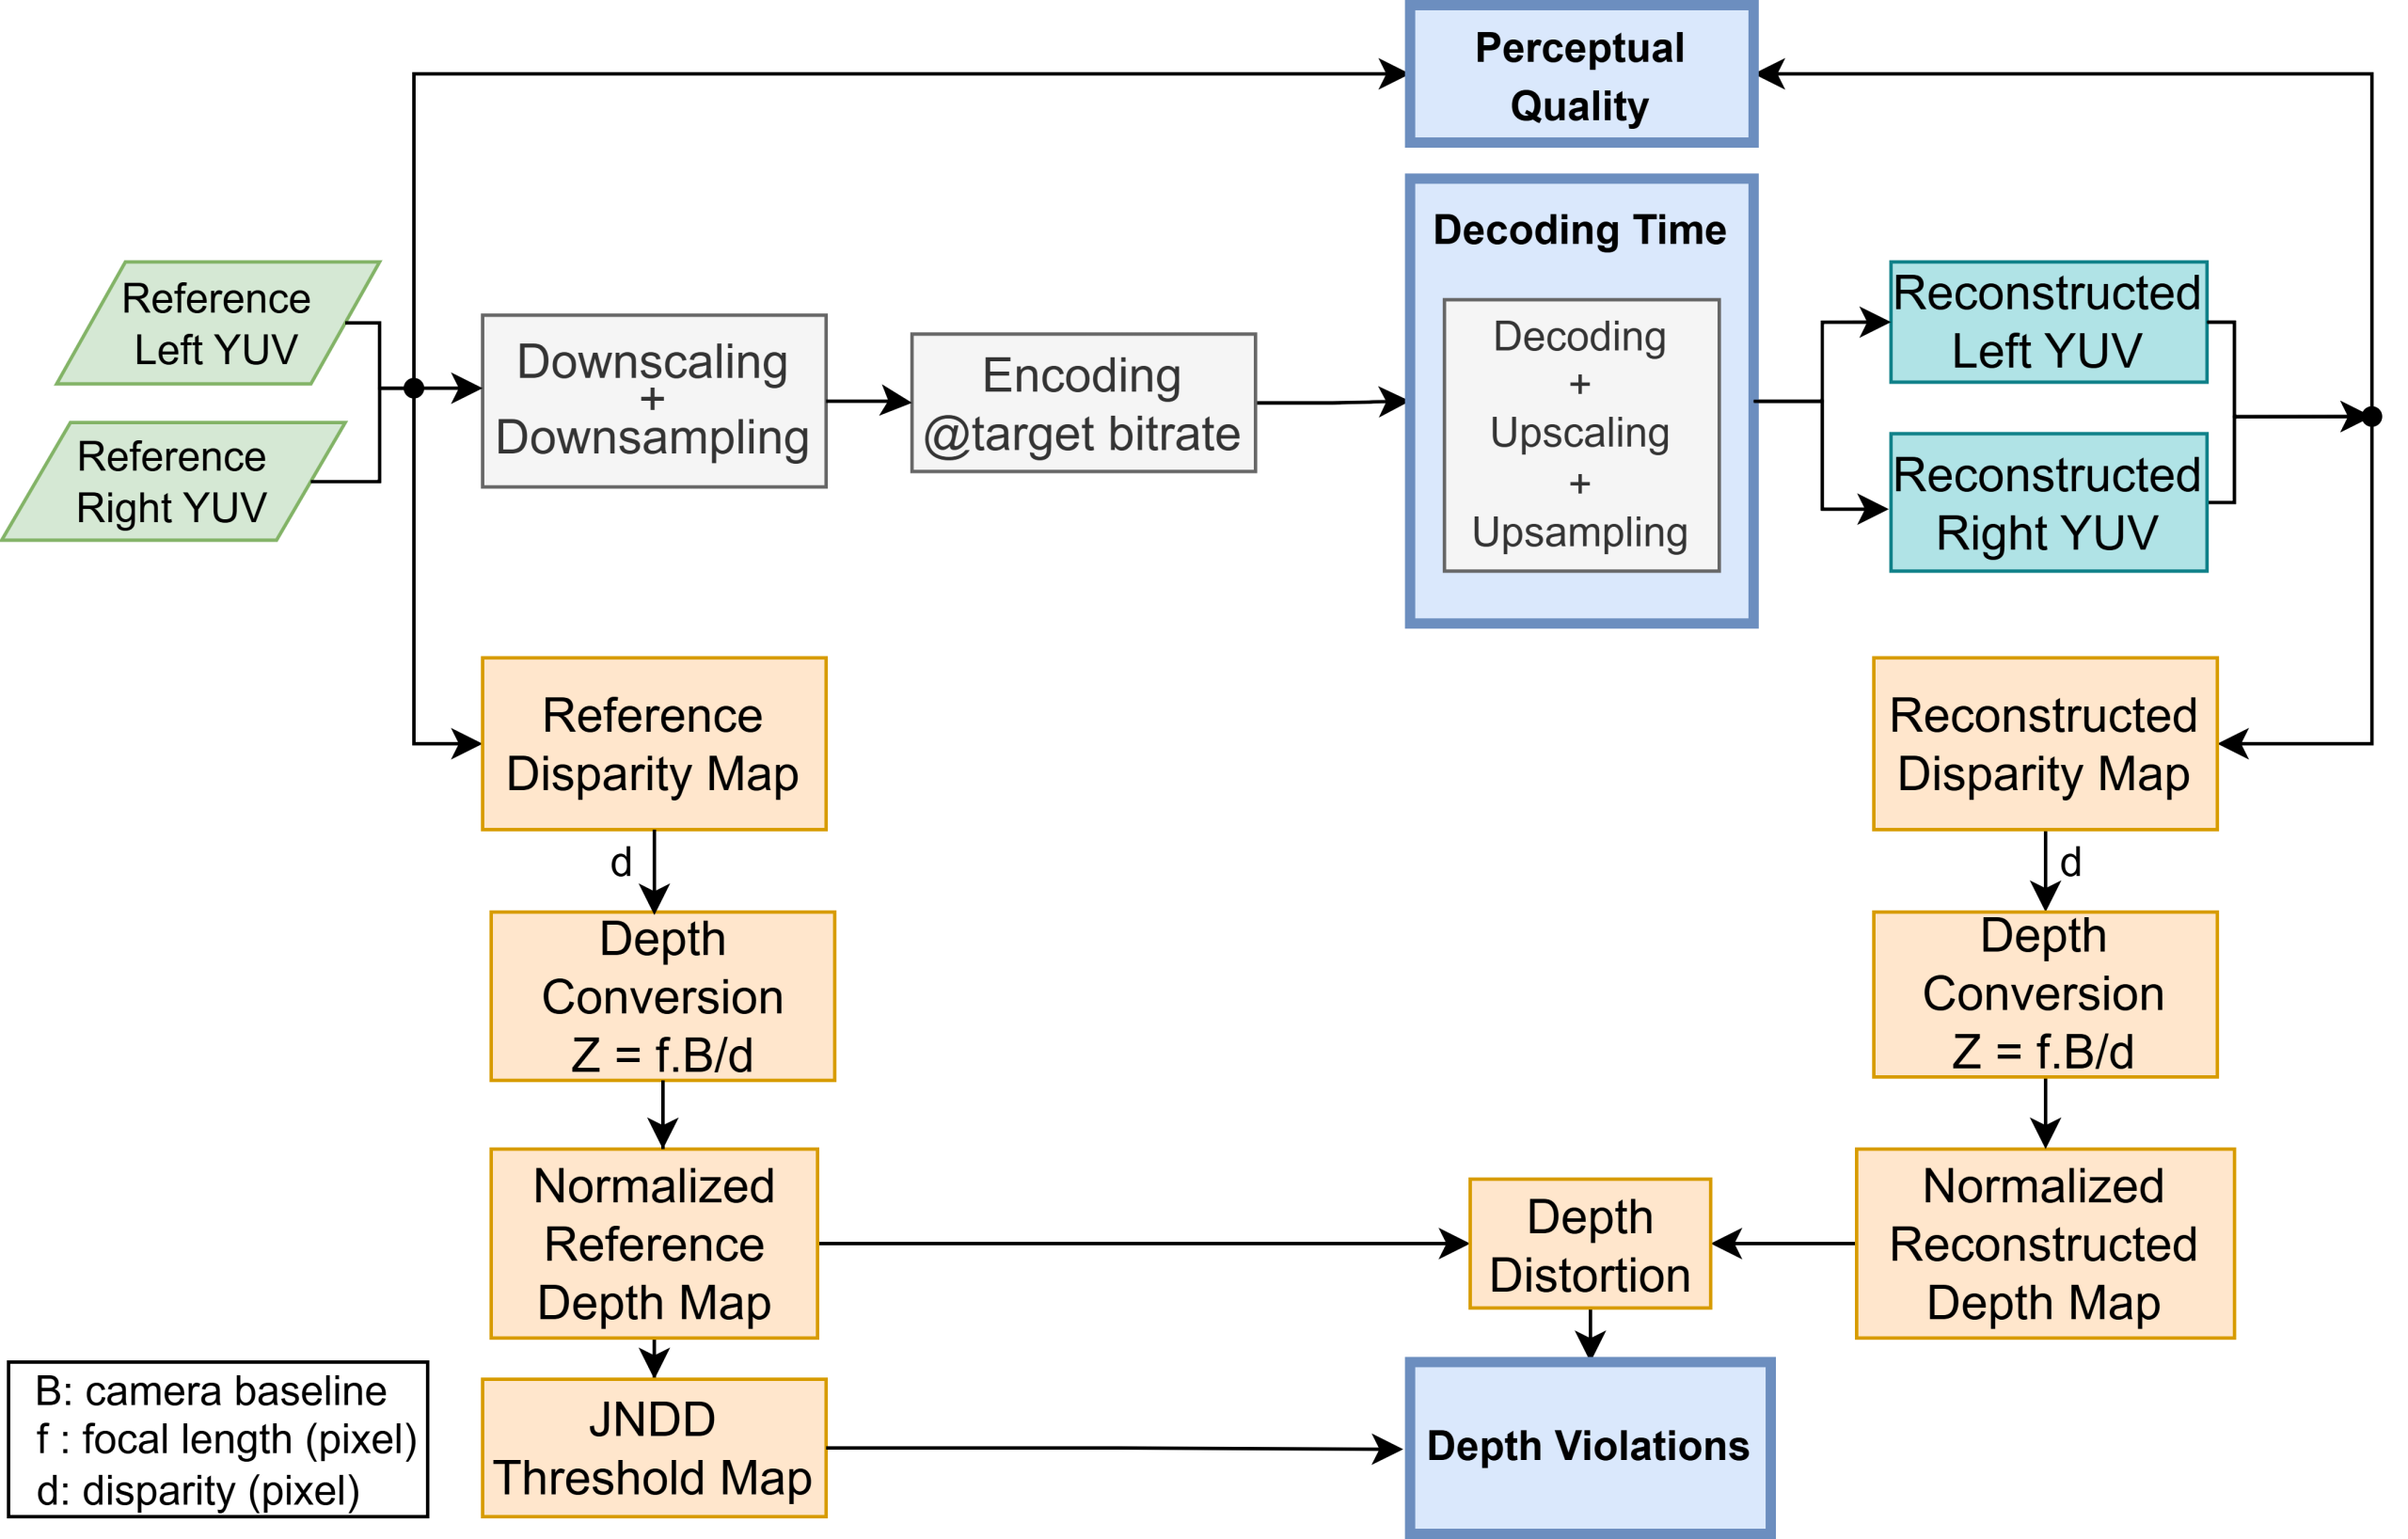
Abstract: Per-title bitrate ladder construction selects bitrate–resolution pairs based on content-specific characteristics, enabling improved compression efficiency compared to static bitrate ladders. Extending content-adaptive bitrate ladder construction to stereoscopic video, we propose a content- and depth-aware stereoscopic bitrate ladder that jointly optimizes three dimensions: (i) perceptual video quality, (ii) depth fidelity, and (iii) decoding efficiency within a unified optimization framework using objective quality metrics Advanced Video Quality Tool (AVQT), Just Noticeable Difference in Depth (JNDD)-filtered depth violations, and decoding time measurements. Bitrate ladder construction is formulated as a binary linear programming optimization problem that selects one representation at each bitrate subject to constraints, with tunable weighting to balance the three objectives. Experimental results demonstrate that the proposed approach achieves a balanced trade-off across perceptual quality, depth fidelity, and decoding efficiency, yielding, on average, a 4.61% BD-rate reduction in perceptual quality, a 2.07% reduction in depth violations, and a 10.49% reduction in decoding time relative to a baseline comprising a fixed bitrate ladder. The resulting bitrate ladders consistently outperform both baselines that optimize individual objectives in isolation and the fixed bitrate ladder, highlighting the benefits of jointly optimizing quality, depth, and decoding efficiency for stereoscopic video streaming.