Bitrate Ladder Analysis for UHD Adaptive Streaming: From AVC to AV2

IEEE International Conference on Visual Communications and Image Processing (VCIP 2026), December 13 – December 16, 2026, Singapore

Authors: Kamran Qureshi (AAU, Austria), Hadi Amirpour (AAU, Austria), Christian Timmerer (AAU, Austria)

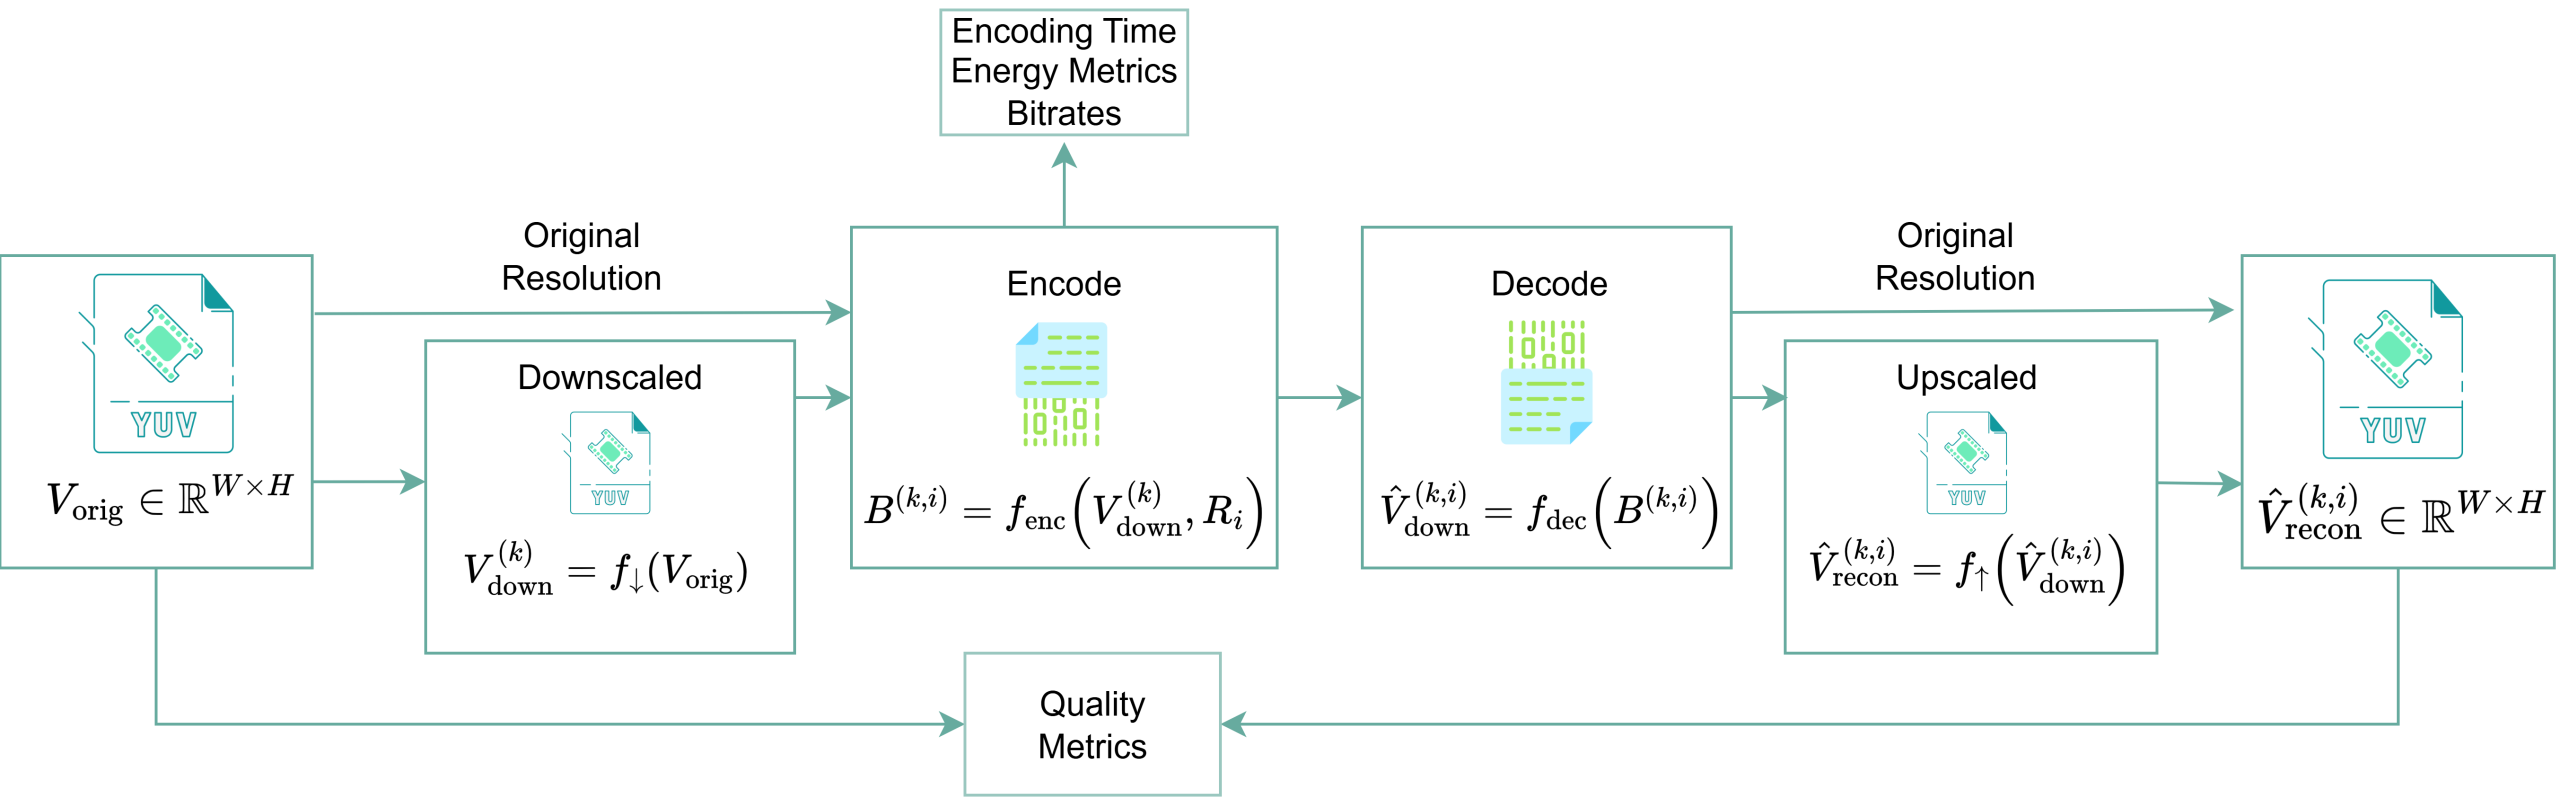
Abstract: Advances in video coding continue to improve compression efficiency for adaptive bitrate (ABR) streaming. However, improved coding efficiency also changes the rate-distortion characteristics of encoded video, thereby altering the resolution transition points and the resulting bitrate ladder for UHD adaptive streaming. A convex-hull-based evaluation was performed to compare codec-dependent bitrate ladders across H.264/AVC, H.265/HEVC, H.266/VVC, AV1, and AV2 using six UHD sequences from the JVET Common Test Conditions. Experimental results showed that higher codec efficiency systematically shifts resolution transition points toward lower bitrates. Relative to AV1, AV2 reduced the median 2160p-1080p transition bitrate by approximately 3x, while the median 1080p-720p and 720p-540p transition bitrates were approximately 9x lower, allowing higher spatial resolutions to remain optimal over a wider bitrate range. Complexity analysis of the evaluated AVC, HEVC, VVC, and AV1 encoders further showed that improved compression efficiency is accompanied by increased encoding time and energy consumption. These findings demonstrate that advances in video compression influence adaptive streaming by modifying the optimal bitrate ladder rather than simply reducing bitrate requirements.
Self-Training for Content-Aware Video Quality
Enhancement in HTTP Adaptive Streaming

IEEE Transactions on Broadcasting

Authors: Yiying Wei (AAU, Austria), Hadi Amirpour (AAU, Austria),  Wei Zhou (Cardiff University, UK), Wassim Hamidouche (TII, UAE) and Christian Timmerer (AAU, Austria)

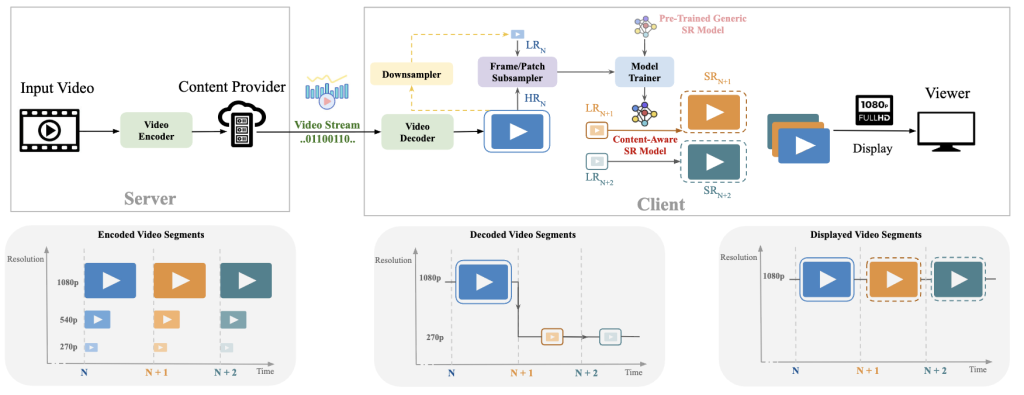
Abstract: Fluctuations in video segment download rates and resolution switching in HTTP Adaptive Streaming (HAS) make it challenging to maintain a consistent Quality of Experience (QoE). However, the impact of such switching is often underestimated, and broadly applicable mitigation strategies remain underexplored. In the past, content-aware approaches have been introduced, using deep neural networks (DNNs) trained on an individual video segment to enhance its quality. These DNNs, transferred as a model stream alongside the video bitstream, allow clients to improve playback quality. However, transferring model streams adds bitrate overhead and additional architectural components, limiting practical use. Furthermore, supporting a wide range of device capabilities with a single DNN is impractical, as it would require device-specific models for each configuration, an approach that becomes unmanageable with increasing device heterogeneity. In this paper, we propose a new self-training method that enables clients to train content-aware video super-resolution (SR) models locally by leveraging previously downloaded high-quality segments. These segments are downscaled and used to train lightweight DNNs, which are then applied to enhance subsequent lower-quality segments. To keep training efficient and real-time, we select only a few predefined frames and extract the most informative patches using a lightweight sampling strategy. Experiments demonstrate that this approach significantly improves visual quality, with average PSNR gains of 1.07 dB (2× upscaling), 0.43 dB (3×), and 0.58 dB (4×) using ESPCN, a lightweight SR approach. To further validate the effectiveness of our approach, we conducted a series of ablation studies to analyze the contributions of individual components. Real-device measurements and end-to-end HAS simulations further show that self-training requires only 2.9–13.0% of a 4-second segment interval on CPU and 1.1–5.3% on GPU across tested mobile devices, while improving VMAF/QoE with only marginal additional rebuffering compared with generic SR.


Efficient Quality Controller for Video Encoding

IEEE Visual Communications and Image Processing Conference (VCIP 2026) – December 13–16, 2026, Singapore

Authors: Yiying Wei (AAU, Austria), Hadi Amirpour (AAU, Austria),  and Christian Timmerer (AAU, Austria)

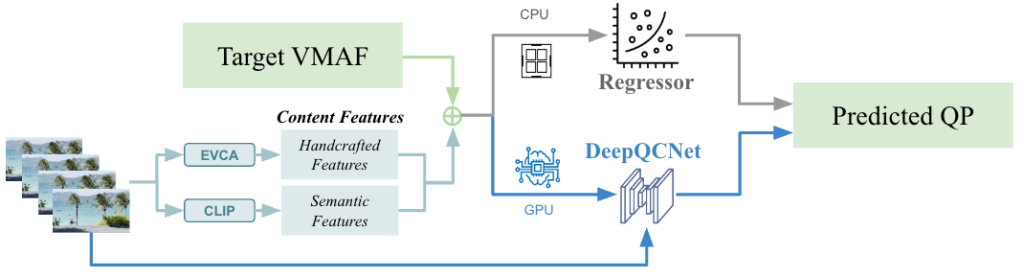
Abstract: Traditional video streaming relies on Adaptive Bitrate (ABR) algorithms that encode videos at fixed bitrate-resolution pairs. As a result, a rate controller is essential to ensure that each encoded representation meets its target bitrate. However, perceptually-aware bitrate ladder construction methods aim to encode videos at a fixed visual quality instead of a fixed bitrate, to avoid under- or over-allocating bits for complex and simple content. In this paper, we propose an efficient quality controller that predicts the Quantization Parameter (QP) required to achieve a target VMAF score for each video segment. The framework supports both CPU-only operation for low-complexity environments and GPU-accelerated inference for improved prediction accuracy. By leveraging content features and target quality levels, our model estimates appropriate QP values without requiring pre-encoding or tight integration with the encoder. For target VMAF scores of 94, 88, and 82, the CPU-only model achieves mean absolute errors (MAEs) of 1.05, 1.24, and 1.34, respectively, comparable to the state-of-the-art errors of 1.14, 1.27, and 1.31, while requiring only a fraction of the computational cost. The GPU-based model further reduces the MAEs to 0.50, 0.49, and 0.47, less than half of the state-of-the-art errors.


Title: 3D Gaussian Splatting Rendering Performance Trade-offs on the Meta Quest 3

Authors: Milad Ghanbari, Hadi Amirpour, Christian Timmerer

Abstract

3D Gaussian Splatting (3DGS) is a compelling technique for real-time view synthesis, but its computational demands pose significant challenges for deployment on resource-constrained standalone eXtended Reality (XR) headsets. This paper presents a systematic performance study of 3DGS rendering on the Meta Quest 3, using a custom interactive tool that enables real-time control of render resolution scale, splat density, and frame rate cap through an in-world interface. We evaluate 180 conditions formed by the factorial combination of six resolution scales (0.5–1.0), ten splat density levels (10–100%), and three camera-to-object distances (0.7 m, 1.1 m, 1.5 m), with each condition repeated ten times. Performance metrics — GPU time, frame rate, GPU utilization, CPU utilization, power draw, and stale frame count — are captured via Meta’s Oculus Virtual Reality (OVR) Metrics Tool at a fixed target frame rate of 72 Hz. The results show that resolution scale is the dominant GPU cost driver due to the quadratic growth in pixel count, while splat density reduction is only an effective performance lever when GPU time is already close to the 72 Hz frame budget. Power draw is determined by total GPU work per time unit rather than cost per frame, which creates a counterintuitive relationship where lower resolution scales draw more power by enabling higher frame rates. These findings expose the interdependence between resolution scale, splat density, frame rate, and power, and establish a quantitative foundation for rendering parameter selection in 3DGS applications on standalone XR hardware.

Title: QoE and Depth Perception in Spatial Augmented Reality Darts

Authors: Milad Ghanbari, Yijue Huang, Wei Zhou, Patrick Le Callet, Christian Timmerer, Hadi Amirpour

Abstract

Accurate depth perception is critical for precision-based interaction in augmented reality applications, particularly in tasks that rely on ballistic motion such as throwing. While recent spatial computing devices support high-fidelity passthrough rendering and controller-free hand tracking, empirical evidence on how users perceive and act upon virtual depth in such environments remains limited. This paper investigates the effect of virtual target distance and time pressure on user performance and quality of experience in a physics-based augmented reality dart-throwing task implemented on the Apple Vision Pro. A controlled, repeated-measures user study with 22 participants evaluated performance at three target distances (near, standard, and far) and under a time-limited condition. Objective measures included score, hit accuracy, and throw timing, while subjective measures captured perceived depth, immersion, control, enjoyment, comfort, progress, time pressure, and adaptation. Results show a clear decrease in throwing accuracy as target distance increased, indicating limits in actionable depth perception despite visually stable spatial rendering. Under time pressure, participants significantly increased throwing speed without a corresponding loss in accuracy, suggesting robust motor execution once the interaction model was learned. Subjective ratings of control and depth understanding remained high across conditions, even when objective performance varied. These findings provide quantitative evidence that modern passthrough augmented reality systems can support reliable controller-free precision interaction, while also clarifying how depth and cognitive demand shape user performance and experience.

Title: EnerGP: Energy Evaluation in Video Game Style Post-Processing

Authors: Milad Ghanbari, Hadi Amirpour, Christian Timmere

Abstract

We present EnerGP, an interactive demo running on the Meta Quest 3 standalone eXtended Reality (XR) headset that enables real-time control over various video game-style post-processing effects in a Virtual Reality (VR) environment. The demo lets users observe the asymmetric relationship between post-processing effects and power consumption. While real-time rendering creates additional GPU overhead for each active post-processing pass, pre-rendered video or streamed video with the same effects baked in, results in measurably lower visual complexity, and thus a reduced hardware-accelerated decoding burden. We validate this finding through a pilot study that used the Enhanced Video Complexity Analyzer (EVCA) by comparing a pre-rendered 3D scene exported with and without seven post-processing effects: (1) Bloom, (2) Depth of Field, (3) Motion Blur, (4) Fog Volume, (5) Color Grading, (6) Screen-Space Ambient Occlusion (SSAO), (7) Temporal Anti-Aliasing (TAA). Results show that post-processing reduces spatial complexity by 17.1% and temporal complexity by 37.1% in the video condition. The demo, deployed on Meta Quest 3, allows users to toggle effects in real time and observe live power and performance metrics via the OVR Metrics Tool.

Title:  Cloud, Edge, or Split? Profiling Onboard and Split Vision-Language Model Deployment for Drone AI

Authors: Zoha Azimi, Reza Farahani, Schahram Dustdar, Christian Timmerer

The 4th International Symposium on Edge Intelligence, Trustworthy and Decentralized Artificial Intelligence (iEDGE 2026) 

October 27-30, 2026 – Paris, France

Abstract:

Vision-Language Models (VLMs) enable edge devices like unmanned aerial vehicles (UAVs) to interpret visual observations and reason about complex environments using natural-language instructions. However, their practical deployment remains challenging as onboard inference is constrained by limited computational, memory, and energy resources, whereas cloud-based inference introduces communication latency, bandwidth overhead, and dependence on network connectivity. To address these limitations, split computing offers a promising alternative by partitioning VLM inference between the resource-constrained UAVs and more capable remote servers. However, the performance trade-offs among fully onboard, cloud-based, and split-computing architectures for lightweight VLMs have not yet been systematically profiled. This paper benchmarks these three deployment paradigms using SmolVLM-256M as a representative lightweight VLM. We quantify their inference latency, computational resource utilization, communication overhead, and energy consumption across varying image resolutions and network conditions. Our results show that no deployment strategy is universally optimal; instead, the preferred strategy depends on the interaction between network conditions and input image resolution.


Konferenz: IEEE AGCS 2026 (Symposium on Edge intelligence, Trustworthy and Decentralized Artificial Intelligence- iEdge)

Wo: 27-30 October 2026, Paris, France.

Titel: A Multi-Node Performance Evaluation of Shared Edge AI Inference

Autoren: Raphael Walcher, Dragi Kimovski, Kurt Horvath

Abstract: 

Edge-based Artificial Intelligence (AI) enables latency-sensitive applications by moving inference closer to data sources. While previous studies have demonstrated the feasibility of inference offloading for individual edge devices, the scalability of shared inference resources under concurrent workloads remains insufficiently understood. This paper experimentally evaluates a multi-node Edge AI architecture in which three roadside units (RSUs) concurrently offload object detection sharing a Zone Processor (ZP) connected through Wi-Fi 6E.

A comprehensive experimental campaign comprising 648 parameter configurations investigates the impact of AI model complexity, capture frame rate, image encoding, and multi-node contention on throughput, latency, and system scalability.

The results demonstrate that inference offloading consistently outperforms local execution on resource-constrained RSUs, reducing end-to-end latency by up to two seconds for computationally demanding models. Throughput analysis further reveals model-dependent computational saturation limits of approximately 18 FPS, 9 FPS, and 3 FPS aggregate throughput for YOLOv5n, YOLOv5s, and YOLOv5m, respectively. Latency component analysis shows that inference execution and the resulting queue waiting account for more than 95% of the end-to-end latency, whereas transmission contributes only a small and nearly constant fraction. These findings establish model complexity and shared inference capacity, rather than communication latency, as the dominant factors governing the performance and scalability of shared Edge AI deployments.

Titel:

In-Service Wind Turbine Blade Inspection: A Multi-UAV Architecture Design and Preliminary Validation

Autoren:

Mario Leopold, Klaus Schöffmann, Farzad Tashtarian

Venue:

IEEE Access


Abstract:

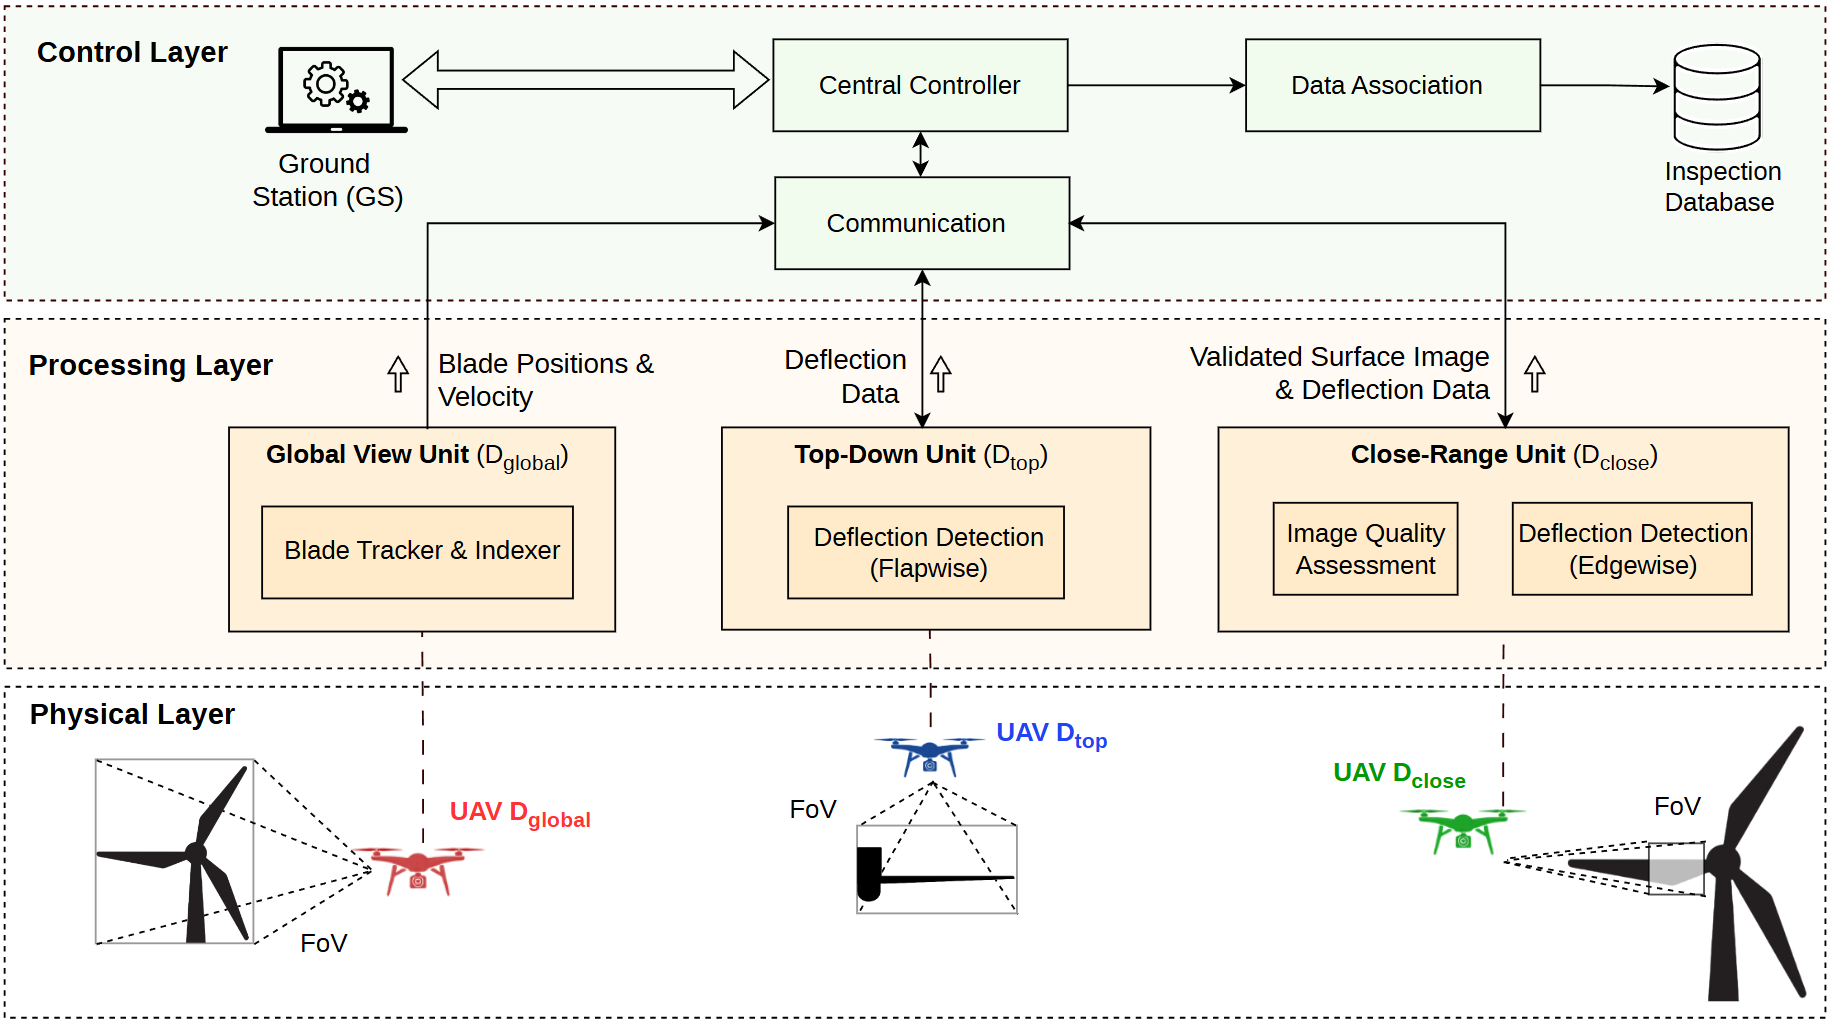
Wind turbine blade inspections are critical for ensuring structural integrity and minimizing operational downtime. However, existing methods, such as single Unmanned Aerial Vehicle (UAV) inspections, are limited by trade-offs among coverage, resolution, operational constraints, and often require turbine shutdown. This paper presents a multi-UAV inspection architecture design for in-service wind turbine blade inspection. The proposed architecture design provides a scalable framework for multi-UAV-based inspection of wind turbines during operation, enabling data acquisition without halting the turbine. The system distributes tasks across multiple UAVs, enabling simultaneous global observation, close-range surface imaging, and deflection detection. A ground station is introduced to coordinate the system, aggregate multi-view data, and offload computationally intensive processing. By separating global and local perception tasks, the architecture addresses key limitations of single-UAV systems and supports synchronized data acquisition during regular wind turbine operation. The core components of the system are implemented and evaluated using a scaled wind turbine model. Results demonstrate stable, persistent blade identification, reliable deflection estimation during rotation, and a component-level preliminary validation on embedded hardware platforms in terms of computational and energy requirements.

Title: DRLM: Deep Reinforcement Learning-Based LLM Query Orchestration in Edge Environments


Authors: Reza Farahani (TU Wien, Austria), Zoha Azimi (AAU, Austria), Mario Colosi (University of Messina, Italy), Lauri Lov\’en (University of Oulu, Finland), Christian Timmerer (AAU, Austria), Schahram Dustdar (TU Wien, Austria)


Venue: IEEE Global Communications Conference (GLOBECOM), Macau S.A.R., China, 7 – 11 December 2026


Abstract:

Large language model (LLM) services increasingly process heterogeneous queries with diverse latency, accuracy, and resource requirements. While edge deployment reduces response time, the heterogeneity of devices and the diversity of model families, parameter scales, and quantization levels make efficient LLM query orchestration challenging. This paper introduces DRLM, a Deep Reinforcement Learning-based LLM query orchestration framework in edge environments. DRLM integrates two lightweight predictors: (i) a class-conditioned quality estimator that maps queries to semantic categories and infers model performance, and (ii) a feature-driven latency predictor that estimates inference time across model-device configurations. These predictions, combined with system state (resource utilization and queue dynamics), feed a factorized Proximal Policy Optimization (PPO) agent that performs state-aware orchestration decisions. To enable data-driven orchestration, we construct a large-scale benchmarking dataset with 223 835 measurements spanning 1258 queries, 6 query classes, 8 model families (32 deployed instances), 5 quantization levels, and heterogeneous edge devices. Evaluation on a realistic 64-node edge cluster and comparison with three baselines and two state-of-the-art methods show that DRLM reduces inference latency by up to 51 % and queuing delay by up to 67 %, while incurring at most 8 % accuracy loss. DRLM further improves latency under increasing workloads up to 61.4 %, demonstrating robust and stable orchestration.